How the architecture works
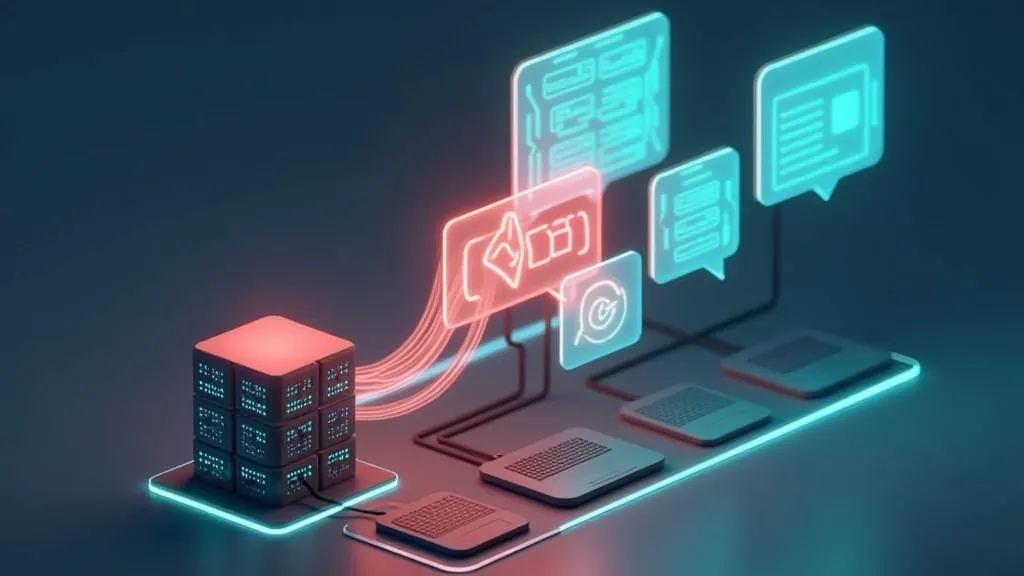
A custom uncensored chatbot has three parts: the user interface, your server and the language API. The server is the center. It stores the API key, keeps the history of each conversation and decides what to send to the model. The interface never talks directly to the API, as that would expose the key.
This API is compatible with OpenAI: the official SDK works by changing the base URL to https://api.llmsemcensura.com/v1 and using the uncensored model. If you don't have a key yet, create one here; signing up gives you US$ 0.50 in free trial credit, with one click.
Before setting up the server, validate the connection with a minimal test in Python, just to make sure the key and URL are correct:
from openai import OpenAI
client = OpenAI(base_url="https://api.llmsemcensura.com/v1", api_key="SUA_CHAVE")
r = client.chat.completions.create(
model="uncensored",
messages=[{"role": "user", "content": "Olá, tudo bem?"}],
)
print(r.choices[0].message.content)The Node server, with streaming
The example uses Express to receive the message and return the response via SSE (server-sent events), so the text appears gradually on the screen. Install dependencies with npm install express openai and set the key in API_KEY.
import express from "express";
import OpenAI from "openai";
const client = new OpenAI({
baseURL: "https://api.llmsemcensura.com/v1",
apiKey: process.env.API_KEY,
});
const SISTEMA =
"Você é a Lia, uma assistente de conversa direta e bem-humorada. " +
"Responda em português do Brasil. Os usuários são adultos.";
const sessoes = new Map(); // id da sessão -> histórico
const app = express();
app.use(express.json());
app.post("/chat", async (req, res) => {
const { id, mensagem } = req.body;
const historico = sessoes.get(id) ?? [];
historico.push({ role: "user", content: mensagem });
res.setHeader("Content-Type", "text/event-stream");
res.setHeader("Cache-Control", "no-cache");
try {
const stream = await client.chat.completions.create({
model: "uncensored",
messages: [{ role: "system", content: SISTEMA }, ...historico.slice(-12)],
stream: true,
max_tokens: 500,
});
let texto = "";
for await (const chunk of stream) {
const parte = chunk.choices[0]?.delta?.content ?? "";
if (parte) {
texto += parte;
res.write("data: " + JSON.stringify(parte) + "\n\n");
}
}
historico.push({ role: "assistant", content: texto });
sessoes.set(id, historico);
res.write("data: [FIM]\n\n");
} catch (e) {
res.write("data: " + JSON.stringify("erro: tente de novo em instantes") + "\n\n");
}
res.end();
});
app.listen(3000);The request body includes a session id and the mensagem. A common mistake is forgetting the Content-Type: application/json header in the call, which leaves the body empty on the server. When testing via the browser or a request tool, you should see the chunks arriving one by one and, at the end, the [FIM] marker.
History: what to keep and what to send
The API has no conversation memory. Each call carries the messages the model needs to see. In the code above, the full history stays in the Map and only the last 12 messages go to the API (historico.slice(-12)).
Why truncate
Without truncation, the input grows with each round and the cost rises accordingly. With a 100,000-token context window, a very long conversation would fit entirely, but it would be expensive and slow without proportional gain.
The system prompt
It defines what the bot is and how it speaks. Short, specific prompts work better than long lists of prohibitions and requirements. Specify the language, tone, average response length, and audience. Each token of the system prompt is resent in every call, so 250 tokens cost much less than 2,000. Test changes one at a time and save the versions that worked.
Long-term memory
If the conversation needs to remember old facts, periodically ask the model for a short summary and place it right after the system prompt. In production, replace the Map with a database, because it resets when the server restarts and does not share state across multiple instances.
How much each message costs
The price is US$ 0.15 per 1M input tokens and US$ 0.50 per 1M output tokens. Example assumptions: 250-token system prompt, 80-token user message, 300-token response and 12 history messages (6 on each side).
- History: 6 x 80 + 6 x 300 = 2,280 tokens
- Input: 250 + 2,280 + 80 = 2,610 tokens, or $0.0003915
- Output: 300 tokens, or US$ 0.00015
- Total: US$ 0.0005415 per message
A thousand messages cost about $0.54. The $0.50 free trial credit lasts for about 923 messages, and a $20 top-up covers about 36,900. To see the top-up tiers and bonuses, open pricing. Failed or rejected requests are not charged.
Limits, 429 and queues
The full key accepts 8 parallel requests and 300 per minute; the trial key, 2 and 60. When a popular chat exceeds this, the API responds with HTTP 429 and the code rate_limited or concurrency. During temporary overload, the 429 comes with Retry-After: 5. Remember that a streaming response holds the slot until the end of the stream, so long responses hold concurrency longer.
A simple retry function respects this interval:
async function comRetry(fn, tentativas = 3) {
for (let i = 0; i < tentativas; i++) {
try {
return await fn();
} catch (e) {
if (e.status === 429 && i < tentativas - 1) {
await new Promise((r) => setTimeout(r, 5000)); // Retry-After: 5
continue;
}
throw e;
}
}
}For many users at once, put a queue on the server and limit how many conversations generate at the same time.
Rules of use for adults
The model is open, hosted by an independent provider, and responds without content refusals for legal adult use. The publisher of such a chatbot assumes responsibility for its use. Some basic practices:
- Age verification. Require confirmation that the user is of legal age before the first conversation and leave this in the terms of your service.
- Prohibition of minors. Sexual content involving minors is prohibited, without exception. Block in your layer any persona or request in this sense.
- Limit per user. Define a daily ceiling of messages to avoid abuse and unexpected spending.
- Privacy. Keep the minimum necessary and state what is stored. In this API, prompts are not used for training.
- Text only. The API does not generate images, audio, or video.
Next steps
With the base ready, the most useful improvements are: saving conversations to a database, showing your balance via the X-Balance-USD header, using tools for the bot to query your data, and JSON mode when you need structured output. The documentation covers each feature. To understand what changes when you remove filters from a model and how that relates to your product, read AI without filters.
Top ups range from US$ 20 to US$ 500, in USDT on the TRC20 network or USDC on the Base network.
